Managed DevOps and Developer Infrastructure Services That Reduce Toil
Modern software teams rely on a growing set of developer infrastructure services: CI/CD pipelines, code review, artifact storage, uptime monitoring, logging and observability, incident response workflows, and operational communication like SMTP POP3 IMAP mail hosting. Each system can look manageable alone, but operating them together—keeping them patched, backed up, monitored, and reliable—quickly turns into a second product. Managed DevOps services reduce that toil by running hosted developer tooling with operational reliability built in. See the Exana home page for the platform and service overview.
At their best, managed DevOps services don’t just “host some servers.” They wrap hosted developer tooling in a reliability layer: server monitoring alerts, uptime monitoring, structured log aggregation, backup and restore testing, security patching, and defined incident response. The goal is predictable delivery infrastructure—so continuous integration and continuous deployment stay fast, reproducible, and dependable instead of becoming a bottleneck.
What Managed DevOps Means in Practice
Managed DevOps is an operating model where a specialized provider runs critical developer infrastructure and reliability products on your behalf, including hosted tooling and the monitoring, logging, and incident response that keep it stable. The provider typically owns day-to-day operations—provisioning, upgrades, capacity planning, performance tuning, and incident response—while your team keeps control of workflows and engineering decisions. Done well, it turns operational burden into clear interfaces, measurable outcomes, and reliable hosted tooling.
A strong engagement begins with clarity around managed DevOps services boundaries. Ownership boundaries should be explicit for DNS, certificates, secrets, on-call rotations, access control, and the monitoring and alerting rules that trigger incident response. When responsibilities are vague, outages turn into handoffs and confusion. When they are clear, incidents become coordinated responses with predictable outcomes and clean escalation paths.
Managed DevOps also implies a commitment to operational reliability for developer infrastructure. That includes service level objectives, realistic recovery targets, and post-incident learning that improves monitoring, logging and observability, and runbooks over time. Reliability is not only about uptime; it is about keeping the developer experience consistent when CI/CD load spikes or a dependency fails. Teams often track this through practical signals like build queue time, CI success rate, mean time to restore, and the number of interruptions caused by flaky hosted developer tooling.
Hosted Tooling That Developers Actually Depend On
Developer infrastructure spans more than a single CI server; it is the hosted tooling ecosystem that turns a commit into a deployable artifact and a traceable change. Managed offerings commonly include Buildbot CI/CD for continuous integration and continuous deployment, plus Phabricator hosting for code review and collaboration. These platforms are powerful, but they demand careful operations: workers need capacity, queues need tuning, and upgrades must be planned and monitored to avoid breaking integrations.
For Buildbot CI/CD, reliability often comes down to worker health, isolation, and repeatability across self-hosted CI runners or managed workers. A managed DevOps service should standardize images, enforce clean workspaces, and keep dependencies pinned so builds don’t change behavior unexpectedly. It should also manage secrets safely for signing, publishing, and deployment steps while providing server monitoring alerts and log aggregation that make failures diagnosable. The value is not merely “CI is running,” but that continuous integration is trustworthy enough that teams stop building workarounds.
Phabricator hosting requires a different operational posture within developer infrastructure: database performance, search indexing, and background workers can degrade gradually and become disruptive at the worst time. A managed DevOps provider can keep response times predictable with uptime monitoring, logging and observability, and proactive maintenance, while handling migrations and validating backups with real restore drills. When hosted developer tooling for code review becomes slow or unreliable, it affects the entire engineering organization, so the operational bar should be high.
Beyond CI/CD and code review, many teams need SMTP POP3 IMAP mail hosting for operational communication: inbound monitoring alerts, outbound notifications, and secure delivery of transactional messages from developer infrastructure systems. Email hosting is deceptively complex due to reputation, deliverability, authentication, and abuse prevention, and it often becomes an unplanned DevOps burden. A managed approach focuses on deliverability and security—SPF, DKIM, DMARC alignment, rate limits, and monitoring for unusual sending patterns—so incident response and operational messages arrive when they matter.
Reliability Products: Monitoring, Logging, and Status Pages
Hosted tooling without observability is a gamble. Uptime monitoring, server monitoring alerts, and logging and observability are the difference between “we think it’s down” and “we know what changed, where, and why.” Managed DevOps services typically provide standardized metrics collection, dashboards, and alert rules aligned to your objectives, plus alert tuning to reduce noise. In managed developer infrastructure, reducing alert fatigue is itself a reliability product because it keeps incident response effective.
Logging should be designed for troubleshooting, not just storage. That means structured logs, consistent fields, sensible retention, and centralized log aggregation that correlates events across CI/CD, Phabricator hosting, and supporting services. When CI failures spike, you want to move from symptom to cause quickly: which workers were affected, which dependency changed, which network path degraded. Actionable observability is what turns log aggregation, metrics, and traces into faster recovery and fewer repeated incidents across managed DevOps services.
Status page hosting is another reliability product that teams often underestimate. When a Buildbot CI/CD cluster or Phabricator hosting environment is degraded, developers need a single, trusted source of truth. Hosted status pages reduce internal chatter, help support teams communicate clearly, and provide a timeline for post-incident review. A managed service should keep the status page operationally separate from the systems it reports on, so it remains available during outages, and should pair it with incident response templates and an update cadence that stays consistent under pressure.
These reliability products work best when they reinforce each other across developer infrastructure. Monitoring detects the issue, logging and observability accelerates diagnosis through log aggregation, and hosted status pages keep stakeholders informed during incident response. The result is fewer interruptions, clearer communication, and managed DevOps services that let engineers focus on shipping instead of firefighting tooling.
How Managed Services Improve CI/CD Outcomes
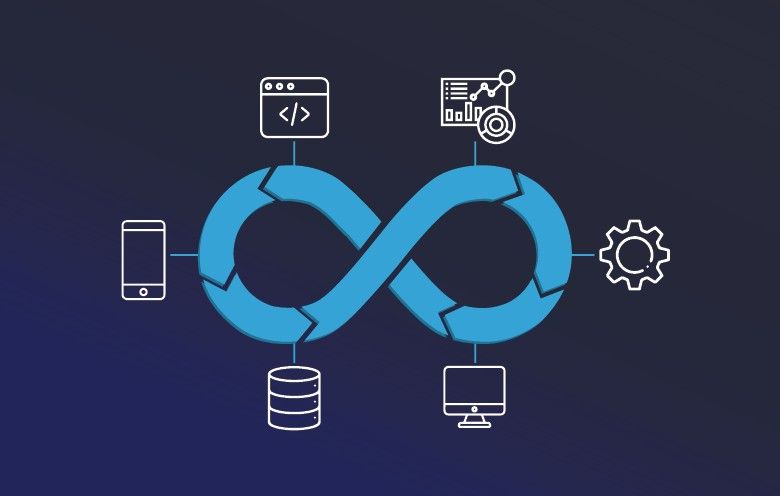
CI/CD is where developer infrastructure quality becomes visible to every engineer. If builds are slow, flaky, or hard to reproduce, productivity suffers and release confidence drops. Managed DevOps improves CI/CD outcomes by treating Buildbot CI/CD and related hosted developer tooling as production systems with performance targets, change control, uptime monitoring, and continuous maintenance that supports continuous integration and continuous deployment.
Capacity planning is a common win for managed DevOps services running CI/CD. Many teams run into build storms after large merges or release branches. A managed provider can scale workers, optimize queue routing, and separate workloads so one noisy project doesn’t starve another, while using server monitoring alerts to catch saturation early. The goal is consistent throughput and predictable lead time from commit to artifact across self-hosted CI runners or managed workers.
Security is another area where managed operations can raise the baseline for hosted developer tooling. CI environments handle secrets, signing keys, and deployment credentials, and they need monitoring and incident response when anomalies occur. A mature service enforces least privilege, rotates credentials, audits access, and supports privacy-first DevOps practices where appropriate. It also applies patches quickly and validates that dependencies and base images remain trustworthy. Secure-by-default pipelines reduce the risk that an attacker uses your build system as a path into production.
Change management matters too for managed DevOps services operating Buildbot CI/CD, Phabricator hosting, and the underlying databases. Upgrades should be staged, tested, and rolled out with rollback plans, with logging and observability validating behavior before and after changes. When upgrades are rushed, teams freeze versions for years and accumulate risk. Managed DevOps can provide a steady cadence of updates that keeps developer infrastructure current without surprise downtime.
Choosing the Right Managed DevOps Partner
The right provider should feel like an extension of your engineering organization, not a ticket-driven black box. Start by evaluating how they run incident response for managed developer infrastructure: do they offer 24/7 coverage, clear escalation paths, and post-incident reports that feed back into monitoring, logging and observability, and runbooks? Ask what they measure over time—uptime monitoring results, alert quality, CI/CD reliability, and restore readiness. Transparent reporting makes reliability work visible and keeps hosted tooling trustworthy.
Next, look at their approach to architecture and portability for hosted developer tooling. Managed DevOps services should improve your posture without locking you into proprietary mechanisms, whether you use self-hosted CI runners, Buildbot CI/CD, or Phabricator hosting. You should understand where your data lives, how backups are stored, how log aggregation is handled, and how you would migrate if needs change. Good providers document runbooks, configuration, and recovery procedures so your team can review and learn from the operational model.
Security and compliance capabilities should match your risk profile for developer infrastructure. That includes access control, audit trails, vulnerability management, separation of duties, and privacy-first DevOps options when sensitive code or logs require stricter handling. If you have requirements around data residency, retention, or email controls for SMTP POP3 IMAP mail hosting, the provider should support them with clear operational practices rather than improvisation.
Finally, consider the developer experience your managed DevOps services create. The goal is smoother daily work: fewer flaky builds, faster feedback loops, clearer incident response communication via hosted status pages, and dependable monitoring and logging and observability when something breaks. When hosted developer tooling disappears into the background because it is well-operated, engineers regain time and attention for product work. That is the promise of managed developer infrastructure: operational reliability for the systems that power delivery.